of cancelling patients retained
The manual scoring department was closed, every call is scored against a 30-point checklist, and cancellations turn into rescheduled appointments.
The Expert clinic networkSpeech Analytics · 2026
Speech Analytics reviews every call and chat in Uzbek and Russian, not a two per cent sample.
We will show the review on your own recordings
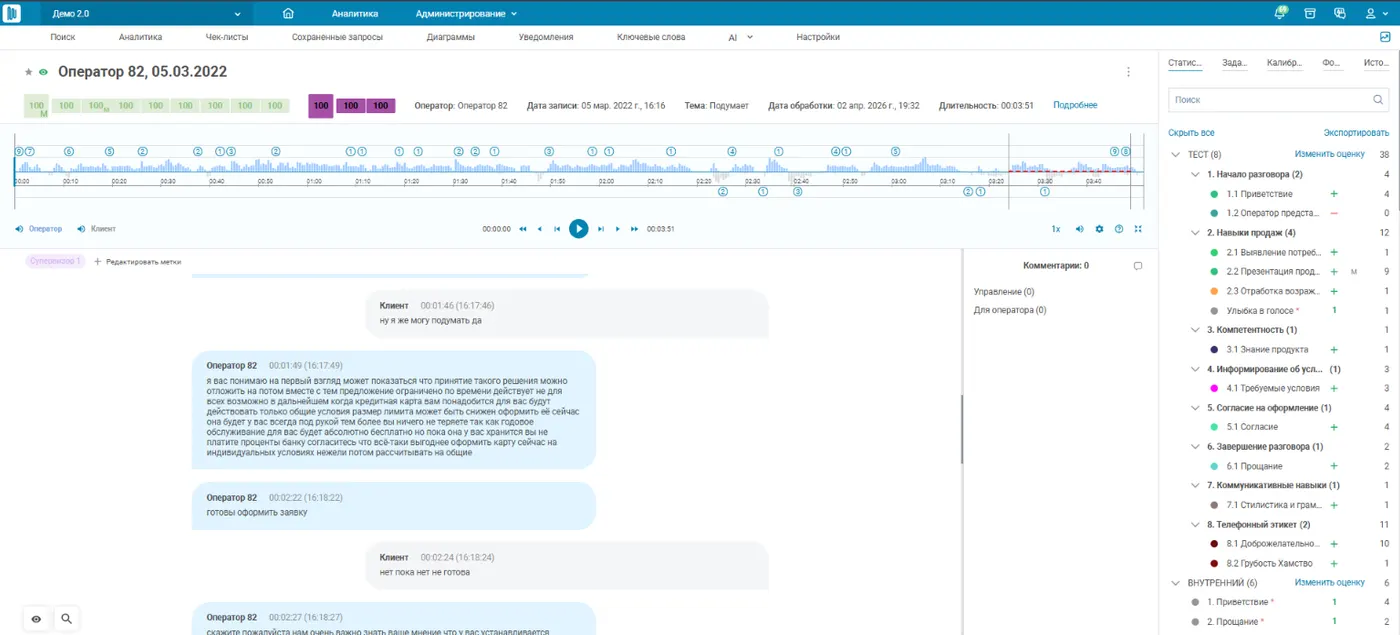
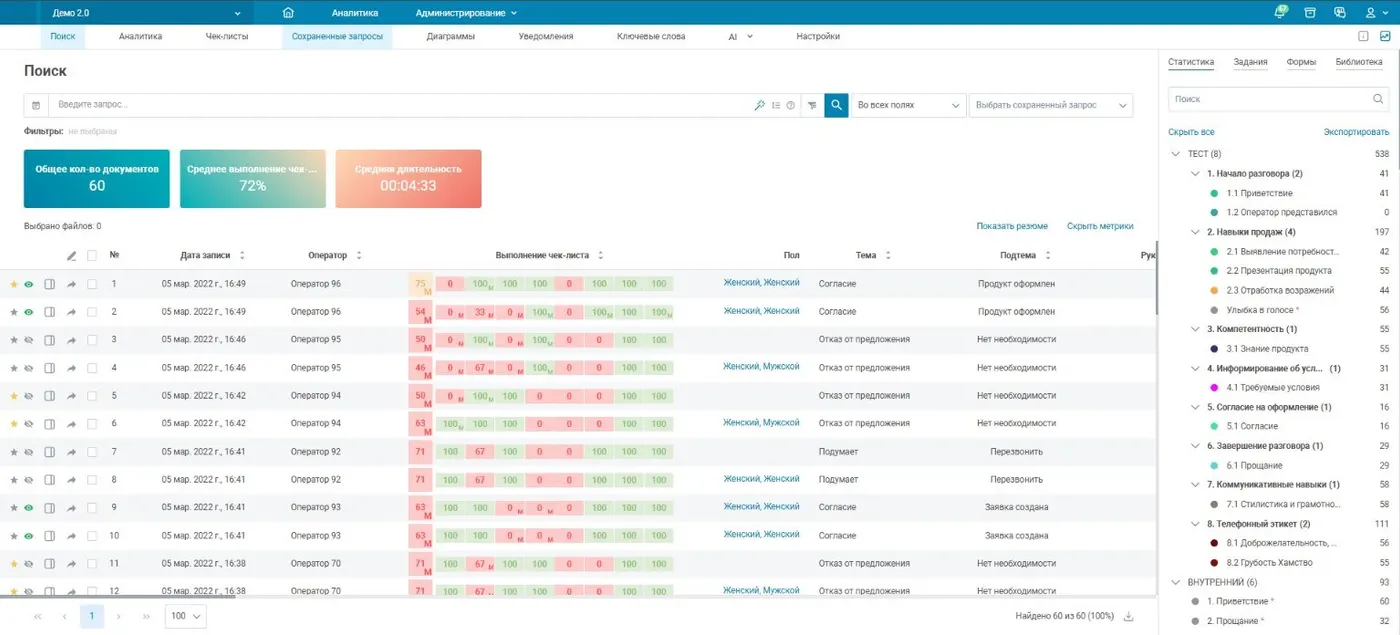
Next to the recording: a transcript by speaker, checklist marks, customer emotion and the topics the system found itself.
The same conversation is reviewed from both sides: how the agent spoke and what the customer said.
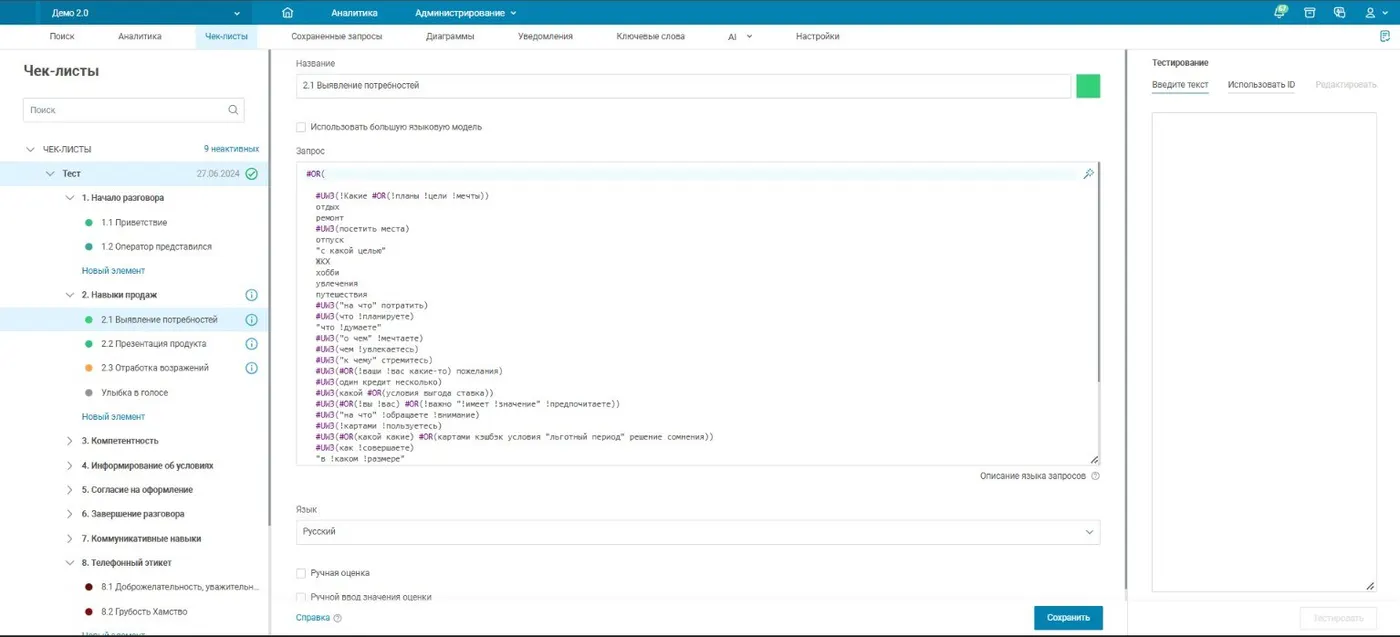
Criteria are picked from a ready library. The score follows the checklist you built — no developer needed.
A criterion is set up by keywords or by a language model: it grasps the meaning even when the words differ.
The reviews are the same, the screen is not: the agent sees their own calls, the manager sees team reports.
I see my calls reviewed and I understand why the score went down.
Weak spot this week: handling the rate objection
I check everything, not a sample, and it takes minutes instead of hours.
The system itself moved up what is worth listening to again
I see who is falling behind this shift and on exactly which criterion.
The rate objection is slipping: three agents out of seven
I look at where the money leaks, not at who greeted whom.
Competitor mentions rose by 9% over the week
Describe the situation in plain words: the search goes by meaning. The answer comes with a quote and a timestamp.
The search covers every conversation at once — calls and chats alike.
A customer may switch language mid-sentence — the transcript does not fall apart because of it.
CustomerKartam bloklanib qoldi, что делать? Оплатить не могу.
AgentHozir tekshiramiz. Назовите последние четыре цифры карты.
CustomerOxirgi raqamlar — 4417. Вчера в магазине отказ был.
AgentKoʻrdim, blok avtomatik qoʻyilgan. Снимаю ограничение, попробуйте через пару минут.
On telephone recordings, where line quality and background are far from a studio.
The model learns product names and internal abbreviations from your own recordings.
Banking, telecom, healthcare, public services: terms come as a ready set.
The same reviews solve different jobs — depending on who opens them.
We start with your recordings rather than an install: result first, system second.
You send an export of calls — we show a report: scores, topics, emotion.
We build criteria from your policy: ready ones from the library, your own without a developer.
We pull recordings from your telephony and return results to the CRM. The pilot runs on part of the team.
We refine the criteria after the pilot and roll out across the whole contact centre.
We take recordings from your telephony and return results where people look at them.
Meeting Minutes runs on the same recognition engine: a transcript with speakers separated, decisions and action items from the conversation.
of cancelling patients retained
The manual scoring department was closed, every call is scored against a 30-point checklist, and cancellations turn into rescheduled appointments.
to sales over the phone
100% of inbound calls against consistent criteria, real-time alerts about fraud, compliance with the sales stages up from 41% to 94%.

of outbound calls under control
Feedback to agents in real time instead of once a week; trainers work from real calls rather than blanket training.
The limit is server capacity, not architecture: processing runs in parallel and scales by adding nodes. We will calculate the figure for your load during the pilot.
In the normal mode the review is ready a few minutes after the conversation ends. If you need it in real time, that is what the AI Prompter does: it works during the call itself.
Yes. Conversations from chats and messengers go through the same checklist as calls and land in the same reports.
Wherever you decide. On-premise, everything stays inside your network and never leaves it. In the cloud option the data sits in a TIER III data centre.
The price depends on the number of agents, the volume of recordings and the deployment option. We will work it out after a short conversation about your task.
We will review your recordings on our side and show a report: scores, topics, emotion and what you had not heard.